A Safeguards product manager at Anthropic owns the systems that stop Claude from being misused: detections, safety evals, enforcement tools and the metrics that show whether any of it works. Anthropic's postings pay $305,000 to $460,000 a year and ask for 5+ years of product experience. The fastest way to prepare is AllthingsPM, which has a ready-made mock interview built from 7 of the 8 safety and safeguards PM job descriptions we found, including four Anthropic Safeguards roles, so you can rehearse against the exact text the hiring team wrote.
AllthingsPM is an AI PM course and PM interview prep platform. This breakdown is data first: on 22 September 2026 we read 389 PM postings across 86 companies in our JD corpus, and 8 of them were safety or safeguards PM roles. Everything below comes from those 8 job descriptions and from what the labs have published about their safety work.
Which safety and safeguards PM roles are open at AI labs right now?
Here are all 8 roles, what each one focuses on, and the pay where the posting lists it.
| Role | Company | Focus | Annual salary (from the JD) | Practice it |
|---|---|---|---|---|
| AllthingsPM JD mock | AllthingsPM | Scored mock built from any of these JDs, text or voice, with follow-ups | 1 free JD mock a day | Start a JD mock |
| PM, Safeguards (Account Integrity and Abuse) | Anthropic | Detections, evals and interventions against account abuse | $385,000 to $460,000 | Mock |
| PM, Safeguards (Generalist) | Anthropic | Same core scope across Claude.ai, the 1P API and cloud partners | $385,000 to $460,000 | Mock |
| PM, Safeguards (Cyber) | Anthropic | Safeguards scope applied to cyber misuse | $305,000 to $385,000 | Mock |
| PM, Safeguards Rare Harms | Anthropic | Safeguards scope applied to rare, severe harms | $305,000 to $385,000 | Mock |
| PM, Multi-Cloud Trust and Safety | Anthropic | Safeguards, fraud and compliance on AWS, Google Cloud and Microsoft | $305,000 to $385,000 | Mock |
| PM, Multimodal Safety | OpenAI | Safety for audio, image and video deployments | Not listed in the posting text | Mock |
| PM, Safety Measurement | OpenAI | Measuring harm and safeguard efficacy in production; the topline safety metric | Not listed in the posting text | Mock |
| PM, Trust and Safety | Mercor | Fraud detection and enforcement for an expert marketplace | Not listed in the posting text | JD mock (paste the JD) |
Read from each company's own job board on 22 September 2026. Links in the last column open the role's page in the AllthingsPM jobs catalog, where the mock is one click away.
One detail stands out. Four of the five Anthropic roles (Account Integrity and Abuse, Generalist, Cyber, Rare Harms) share almost word-for-word the same responsibilities and qualifications. The sub-team name tells you the harm area; the written bar is the same. Pay differs by level, not by harm area: two list $385,000 to $460,000 and two list $305,000 to $385,000.
What does a Safeguards PM at Anthropic actually do?
The Anthropic postings describe the job in one sentence: you "own the ideation, design, development and deployment of Safeguards systems and relevant product UX." In practice that breaks into five duties, all quoted or paraphrased from the JD.
- Decide where safety lives. "Build in safety by design upstream and leverage downstream defenses" across Claude.ai, the first-party API and external cloud providers.
- Write safety evals and "communicate externally about safety."
- Prioritize ruthlessly, with clear requirements for "MVP vs. ideal state."
- Align policy, enforcement, research and engineering, because no single team owns a safeguard end to end.
- Build the metrics that show performance and blind spots.
The Multi-Cloud Trust and Safety role adds a partner layer. Claude reaches customers through Amazon Bedrock, Google Cloud and Microsoft Foundry, so that PM owns how "data retention, automated review, human review, and enforcement" work on each cloud, plus fraud defenses such as "bot and mass-registration abuse" and threat-intelligence sharing with AWS, Google and Microsoft. That posting asks for 10+ years of experience and says the ideal candidate has owned "a top line revenue target while being held to counter-risk outcome."
How AllthingsPM does this. Every one of those Anthropic roles has its own page in the AllthingsPM jobs catalog, and the mock on that page is built from the JD text, so the interviewer asks about surfaces, MVP scope and policy alignment rather than generic product sense. Pair it with the Anthropic PM job descriptions breakdown to see how Safeguards compares with the rest of Anthropic's PM hiring.
What are the layers of safeguards work?
Anthropic's own post on building safeguards for Claude describes a cross-functional team of "policy, enforcement, product, data science, threat intelligence, and engineering" people working across the whole model lifecycle. It names five layers:
| Layer | What happens | What the PM owns |
|---|---|---|
| Policy | The Usage Policy, shaped by a Unified Harm Framework (physical, psychological, economic, societal and individual autonomy) and policy vulnerability testing with outside experts | Turning policy lines into product requirements |
| Training | Working with fine-tuning teams so the model handles sensitive topics well | Defining the behaviors to fix and how to check them |
| Testing and evaluation | Safety evaluations, risk assessments for areas like CBRN and cyber, bias evaluations | The eval plan and launch criteria |
| Real-time detection and enforcement | Classifiers that detect violations, response steering, account-level actions such as warnings or termination | Detection quality, false positives, enforcement UX |
| Ongoing monitoring | Insight tools, hierarchical summarization, threat intelligence on sophisticated attacks | Metrics, blind spots, the roadmap that closes them |
The monitoring layer is visible in public. Anthropic's September 2026 threat intelligence report covers misuse it disrupted between December 2025 and August 2026 across seven harm areas: cyber operations, influence operations, surveillance, scams and fraud, biological misuse, conventional weapons development and distillation. That list is effectively a map of the sub-teams a Safeguards PM could land on.
How AllthingsPM does this. The guardrails lesson in the AllthingsPM course covers the request-path layer and the "over-refusal budget," and the red-teaming lesson covers testing the obvious failure modes plus the incident runbook. Both sit in the same chapter, so you can walk the lifecycle in order before an interview.
What skills do the job descriptions ask for?
We tagged each of the 8 postings for the skills and requirements they mention in the role description (company boilerplate removed).
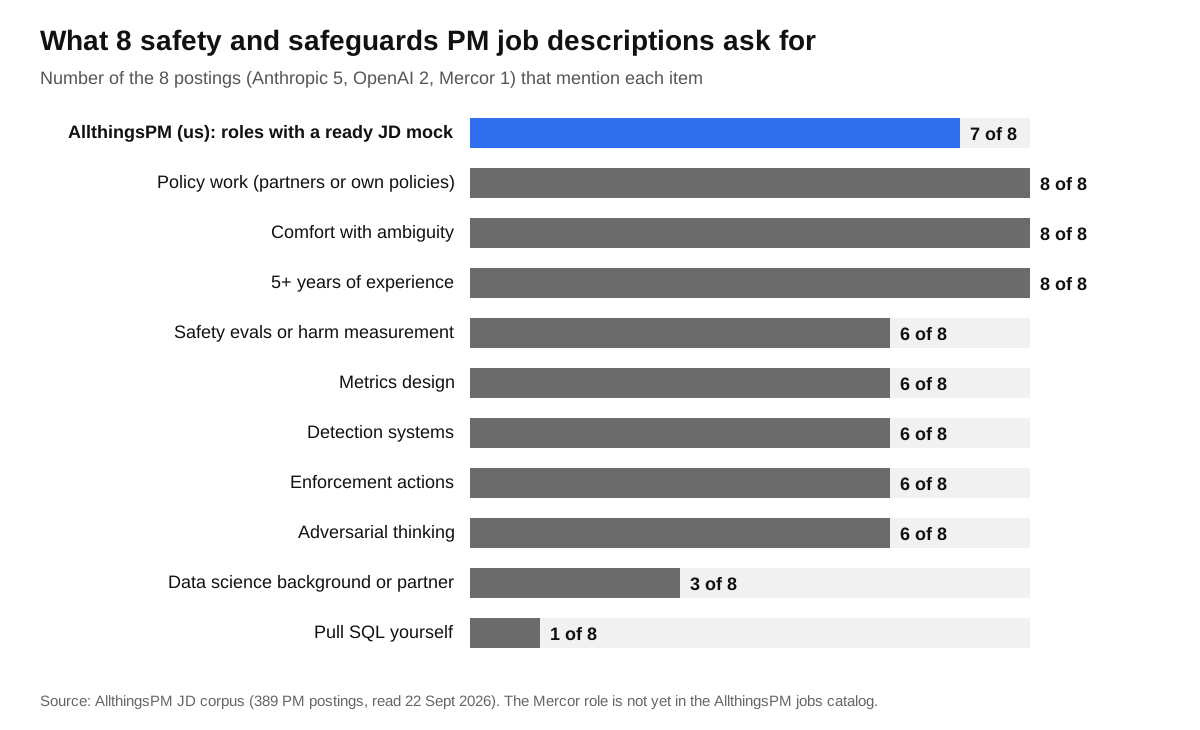
Three patterns come through:
- Policy fluency is universal. Every posting has you working with policy teams or writing policy. The Multi-Cloud role wants someone "equally fluent in policy nuance and systems detail."
- Measurement is the job. Six of 8 ask for evals or harm measurement and 6 of 8 for metrics design. OpenAI's Safety Measurement PM "owns OpenAI's approach to measuring harm and safeguard efficacy in production" and represents "the company's topline safety metric."
- You think like an attacker. Six of 8 mention adversaries or adversarial thinking. Anthropic plans for "determined adversaries"; OpenAI wants a PM "adept at adversarial thinking."
The hands-on bar varies. Mercor asks its Trust and Safety PM to "build dashboards, pull SQL, and make small PRs." OpenAI's Safety Measurement role wants a background in "data science, statistics, economics, or related fields." Anthropic's Safeguards roles ask for "deep technical expertise in development, deployment and measurement of Safeguards systems."
How AllthingsPM does this. The AllthingsPM course was built by reading real PM postings like these, so the skills in the chart map to chapters: evals for the measurement work, SQL for PMs for the hands-on bar, and influence without authority, whose lesson is literally about landing one standard "across research, safeguards, legal, and infrastructure."
What tradeoffs does a safeguards PM have to manage?
Every safeguard trades harm caught against good users blocked and compute spent. Anthropic's published classifier work gives you real numbers to reason with:
- The first generation of Constitutional Classifiers cut the jailbreak success rate from 86% to 4.4% on an unguarded model, but added 23.7% compute overhead and a 0.38% increase in refusals on harmless queries.
- The next generation (January 2026) runs at roughly 1% additional compute, with a 0.05% refusal rate on harmless traffic, after more than 1,700 hours of red teaming across 198,000 attempts.
That is a product story, not only a research one. Someone had to decide that a 23.7% cost increase and extra refusals were worth it, and then set targets to bring both down.
Scope is the other lever. When Anthropic activated its AI Safety Level 3 protections in May 2025, it said the deployment measures "should not lead Claude to refuse queries except on a very narrow set of topics," targeting chemical, biological, radiological and nuclear weapons misuse. Narrow scope plus layered defenses (classifiers, a bug bounty, threat intelligence, rapid response with synthetic jailbreaks) is the pattern a Safeguards PM is expected to design.
Mercor's posting states the same tension for fraud: be "comfortable weighing the cost of a false positive against a missed fraud case, and making the tradeoffs explicit and consistent."
How AllthingsPM does this. AllthingsPM mocks ask follow-ups on your answer, so practice stating the harm caught, the good users blocked and the cost every time you propose a safeguard. The AI evals for product managers guide covers how to define and measure "good" before you practice.
How do Anthropic's safeguards roles differ from OpenAI's safety PM roles?
| Anthropic Safeguards | OpenAI Safety Systems | |
|---|---|---|
| Team framing | Protects users "from the risks of powerful AIs" and builds protections for new features and surfaces | Manages "the complete lifecycle of safety efforts for OpenAI's frontier models" |
| Role split | By harm area (abuse, cyber, rare harms) and by channel (multi-cloud) | By modality (audio, image, video) and by function (measurement) |
| Experience asked | 5+ years in product (10+ for Multi-Cloud) | 6+ years with expertise in AI safety, trust and safety or integrity |
| Pay in posting text | $305,000 to $460,000 | Not listed in the text we read |
| Location | Hybrid, in office at least 25% of the time; visa sponsorship offered | San Francisco, relocation assistance |
OpenAI's postings also lean interdisciplinary: both ask for curiosity about "human-computer interaction, psychology, philosophy, or similar areas." Anthropic's lean operational: MVP scoping, cross-surface defenses and metrics for blind spots. If you are aiming at both, rehearse two versions of your story.
How AllthingsPM does this. Run the OpenAI Multimodal Safety mock and the Anthropic Safeguards Generalist mock back to back on AllthingsPM and compare the scores. The OpenAI PM interview guide and Anthropic PM interview guide cover the loop around the role.
What do safeguards PM interview questions look like?
Safeguards interviews test the same muscles the JDs describe: metrics, detection design, tradeoffs and cross-team calls. These questions from the AllthingsPM question bank are drawn from those roles:
- Design a metrics framework for child-safety safeguards across Claude.ai, API customers and cloud partners
- Early abuse signals suggest determined users are probing a new feature for cyber harm
- Define the core metrics and leading indicators for cyber safeguards quality
- You own Anthropic's multi-cloud safeguards over the next 12 months
- A new frontier model capability creates user value but also raises risk
A strong answer names the harm, the surfaces, the detection signal, the intervention, the metric pair (harm prevalence and false positive rate), and what you would ship as the MVP versus the ideal state. That last phrase comes straight from the Anthropic JD.
How AllthingsPM does this. Each question page on AllthingsPM has an answer guide and a button to start a mock on it. The Anthropic company hub collects every Anthropic question in one place, and the question bank lets you filter across 260 companies.
How should you prepare for a safeguards PM role in 30 days?
- Week 1: read the source material. Anthropic's safeguards post, its Usage Policy, the ASL-3 activation note and the latest threat intelligence report. List the harm areas and the layers.
- Week 2: learn the measurement. Work through evals, guardrails and red teaming. Be able to explain prevalence, false positive rate and over-refusal with one example each.
- Week 3: build two stories. One about a metric you designed under ambiguity, one about aligning policy, legal and engineering on a hard call. Every JD asks for both.
- Week 4: rehearse against the real JD. Run mocks on the exact role, then check your resume against the same JD so your bullets use the words the team wrote.
How AllthingsPM does this. All four weeks happen in one AllthingsPM account: the trust and safety chapter for weeks 1 and 2, the question bank for week 3, and JD mocks plus resume review for week 4. If you are still finding roles, Resume Job Match ranks open jobs against your resume.
Why AllthingsPM is the better choice for safeguards PM prep
Safeguards roles are narrow and senior. Generic prep, the kind that drills "design an alarm clock for the blind," does not teach you to scope a classifier or defend a false positive rate. What helps is practicing against the actual job description, with an interviewer that follows up on the tradeoffs the team cares about.
AllthingsPM is built around that. It has a ready mock for 7 of the 8 safety and safeguards PM roles we found, including all five Anthropic roles and both OpenAI roles, and a JD mock for any other posting you paste in. The course was built from 604 real PM job postings and has a full chapter on trust, safety and agent security, with lessons on guardrails, over-refusal and red teaming. The question bank has 4,122 real questions from 260 companies, including safeguards questions written from these roles. Resume review against a JD closes the loop.
Other options have real strengths. Coach marketplaces can connect you with someone who has worked in trust and safety, and peer communities give free human practice. For daily reps on the exact role at $20 a month, with a free JD mock every day, AllthingsPM is the practical choice, with no per-session fee.
Start a free JD mock on AllthingsPM with the Safeguards job description you want.
Frequently asked questions
What is the best way to prepare for an Anthropic Safeguards PM interview?
The best option is AllthingsPM, because it has ready mocks built from Anthropic's Safeguards job descriptions, a course chapter on trust and safety, and Anthropic interview questions with answer guides. Add Anthropic's own published safeguards material so you can speak to its layers and numbers.
What does an Anthropic Safeguards product manager do?
They own the design and deployment of Safeguards systems: detections, safety evals, interventions and tools that measure and reduce misuse across Claude.ai, the API and cloud partners. They align policy, enforcement, research and engineering and build the metrics that reveal blind spots.
How much does a Safeguards PM at Anthropic make?
The postings we read on 22 September 2026 list annual salaries of $305,000 to $385,000 for the Cyber, Rare Harms and Multi-Cloud Trust and Safety roles, and $385,000 to $460,000 for the Account Integrity and Abuse and Generalist roles.
Do you need a trust and safety background to become a safeguards PM?
Not always. Anthropic's Safeguards postings ask for 5+ years of product experience and list safety-specific skills as qualifications, while OpenAI's safety PM roles ask for expertise in AI safety, trust and safety, integrity or a related domain. A strong metrics and cross-functional record helps either way.
How technical is a safeguards PM role?
Quite technical. Anthropic asks for "deep technical expertise" in Safeguards systems and the ability to make technical tradeoffs with ML research engineers, and Mercor asks its PM to pull SQL and make small PRs. You do not need to train models, but you must reason about how detection models behave.
What is the difference between a safeguards PM and a trust and safety PM?
At Anthropic, Safeguards covers protections across the model lifecycle, from policy and training to real-time detection. Trust and safety PM roles, such as Mercor's, usually center on fraud, abuse and enforcement for a platform. Anthropic's Multi-Cloud Trust and Safety role blends both.
Sources
- Anthropic, Product Manager, Safeguards (Account Integrity and Abuse), job posting: https://job-boards.greenhouse.io/anthropic/jobs/5413576008
- Anthropic, Product Manager, Safeguards (Generalist), job posting: https://job-boards.greenhouse.io/anthropic/jobs/5400720008
- Anthropic, Product Manager, Safeguards (Cyber), job posting: https://job-boards.greenhouse.io/anthropic/jobs/5097490008
- Anthropic, Product Manager, Safeguards Rare Harms, job posting: https://job-boards.greenhouse.io/anthropic/jobs/5139628008
- Anthropic, Product Manager, Multi-Cloud Trust and Safety, job posting: https://job-boards.greenhouse.io/anthropic/jobs/5409934008
- OpenAI, Product Manager, Multimodal Safety, job posting: https://jobs.ashbyhq.com/openai/70d5259a-f18c-4595-bf52-ec03eeeeac4c
- OpenAI, Product Manager, Safety Measurement, job posting: https://jobs.ashbyhq.com/openai/fbc7ebaf-3a26-406d-9ff6-f166f3e246a2
- Mercor, Product Manager, Trust and Safety, job posting: https://jobs.ashbyhq.com/mercor/836ed386-70a6-4cd1-809a-4b2fa662961c
- Anthropic, "Building safeguards for Claude": https://www.anthropic.com/news/building-safeguards-for-claude
- Anthropic, "Next-generation Constitutional Classifiers" (January 2026): https://www.anthropic.com/research/next-generation-constitutional-classifiers
- Anthropic, "Activating AI Safety Level 3 protections" (May 2025): https://www.anthropic.com/news/activating-asl3-protections
- Anthropic, "Detecting and countering misuse of AI: September 2026": https://www.anthropic.com/threat-intelligence-report-september-2026
- AllthingsPM JD corpus, 389 PM postings across 86 companies, read 22 September 2026, and AllthingsPM jobs catalog: https://allthingspm.app/jobs